The Unstract Blog

Product features, releases, updates, roadmaps, and everything in between AI, automation, and data.

PDF Hell and Practical RAG Applications
Product

PDF Hell and Practical RAG Applications

Extracting text from PDFs often poses significant challenges, especially for applications in RAG, NLP, and large language models (LLMs). In this article, we delve into some challenges.

Read More »
Product

LLMWhisperer: Amazon Textract Alternative

LLMWhisperer and Textract are both powerful OCR tools, but LLMWhisperer excels in preserving layout and handling complex documents more accurately. For businesses needing precise structured data extraction and cost-effectiveness, LLMWhisperer is the better choice.

Read More »
Unstract is document agnostic. Works with any document without prior training or templates.
Have a specific document or use case in mind? Talk to us, and let's take a look together.

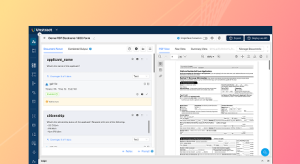
Prompt engineering Interface for Document Extraction

Prompt engineering Interface for Document Extraction

Make LLM-extracted data accurate and reliable

Use MCP to integrate Unstract with your existing stack

Control and trust, backed by human verification

Make LLM-extracted data accurate and reliable

LATEST WEBINAR

CLI + MCP: Document extraction pipelines for batch jobs and AI agents

October 22, 2026