Product
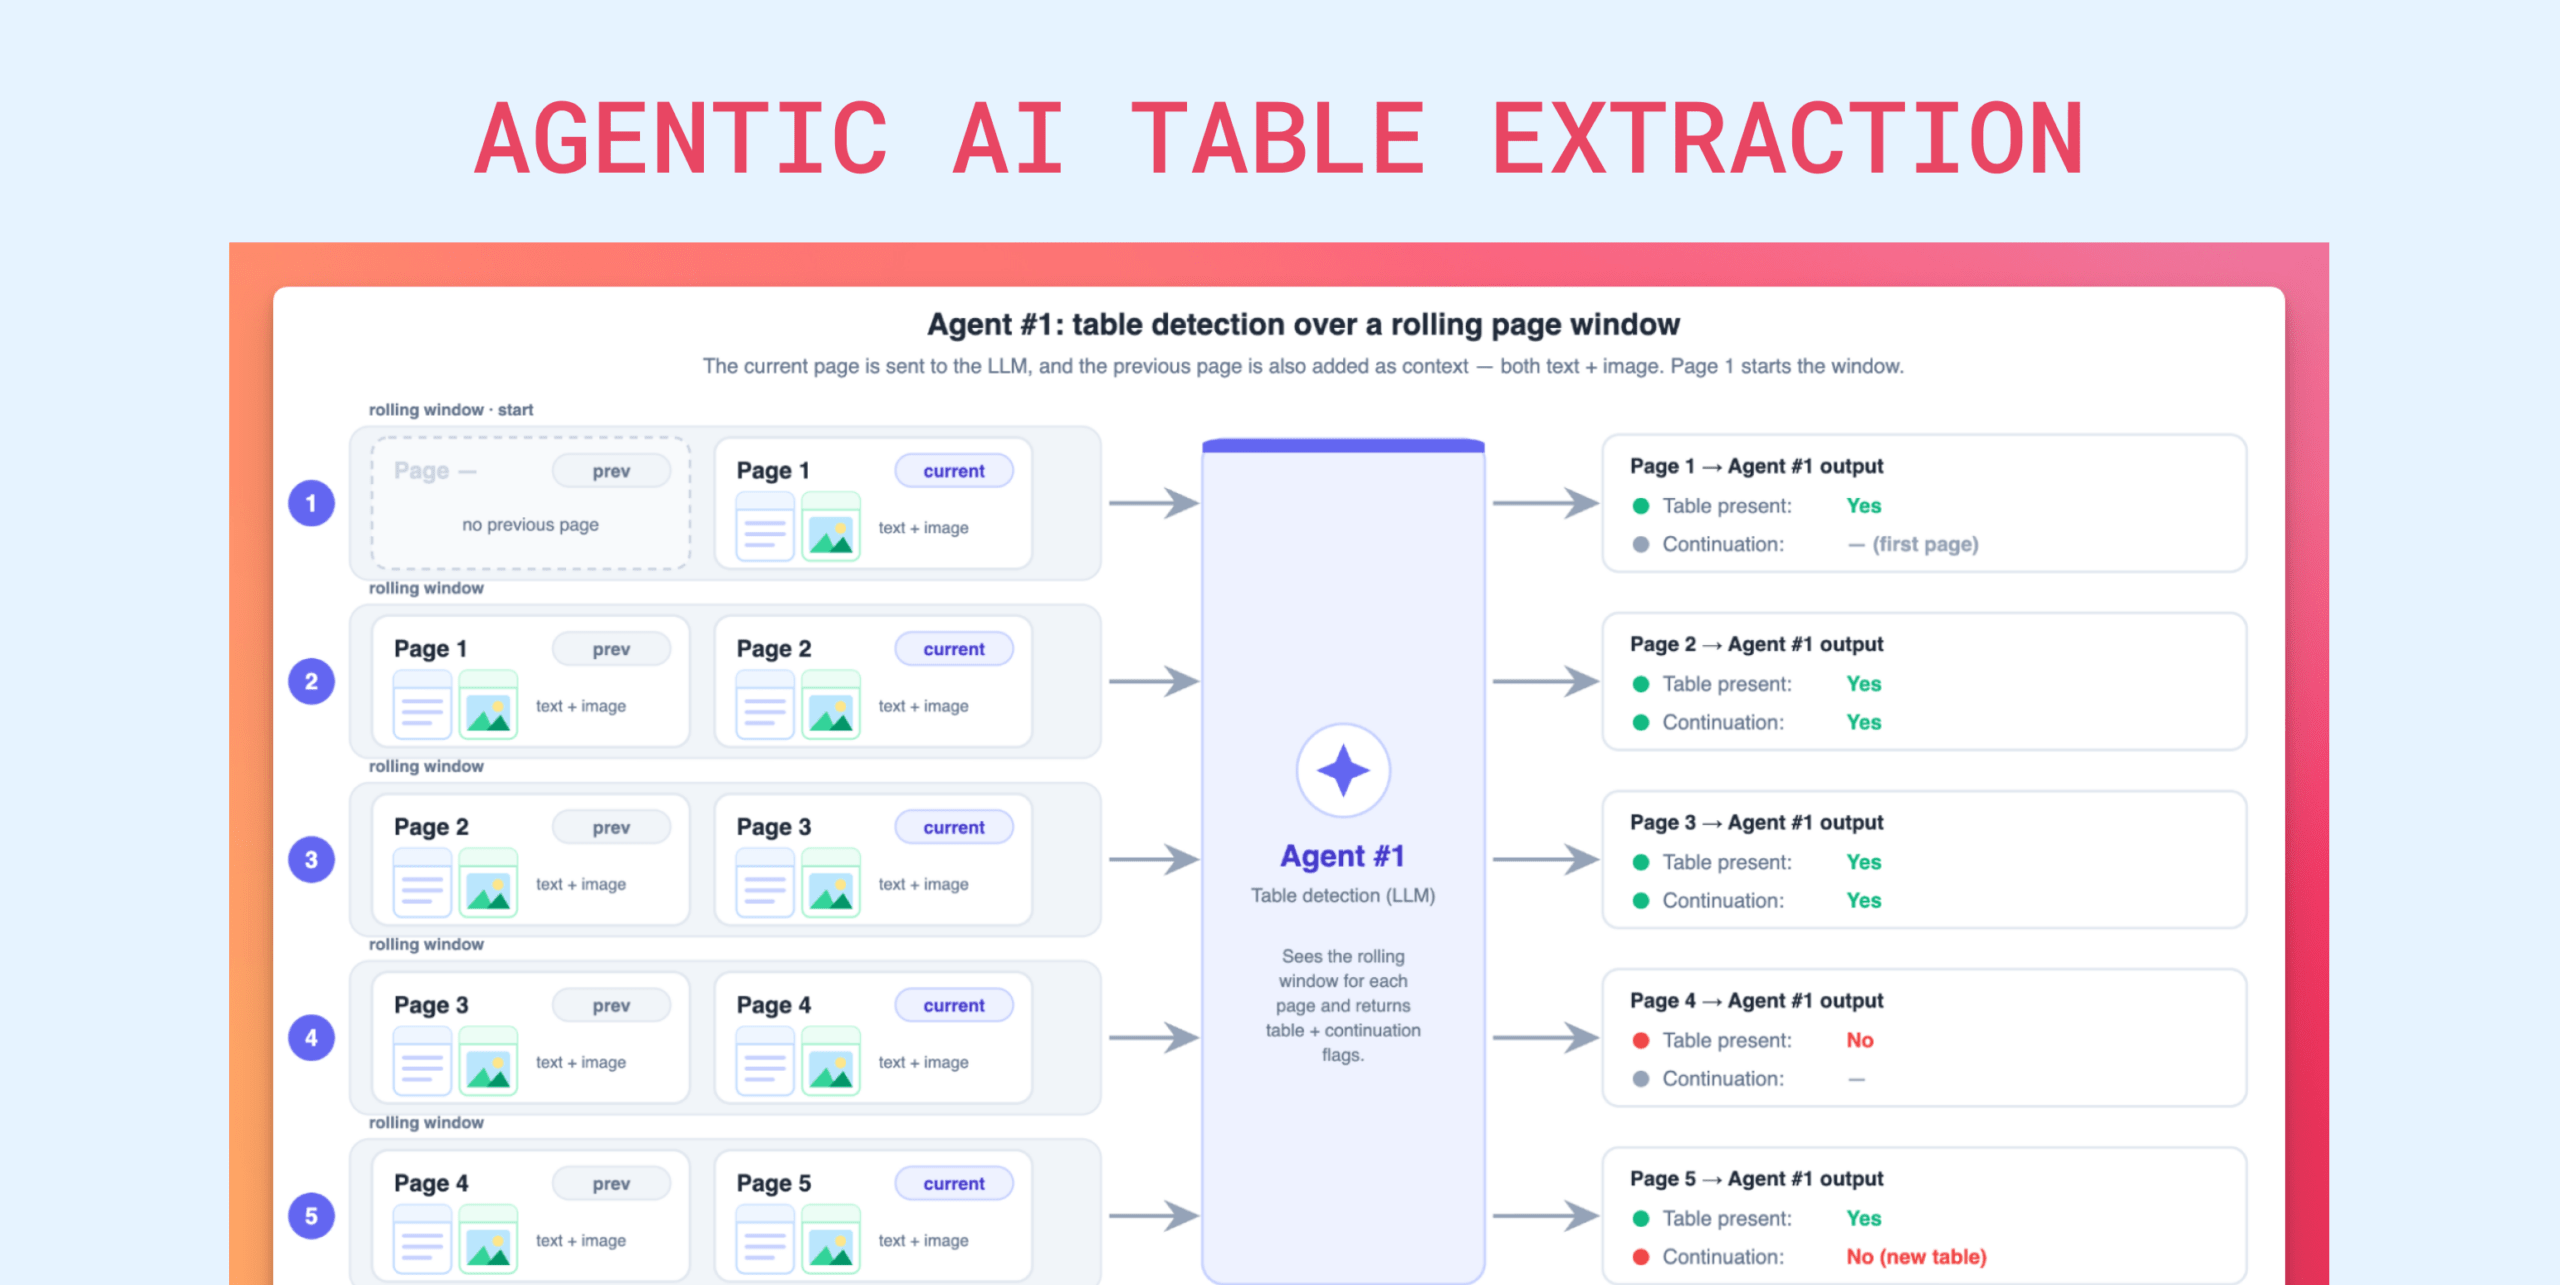
Stop Fighting Messy Tables: Why We Split PDF Table Extraction Across 6 Agents and a Codegen Step
Extraction demos are easy. We can build one in an afternoon, and so can anyone. Clean document in, clean JSON

Extraction demos are easy. We can build one in an afternoon, and so can anyone. Clean document in, clean JSON
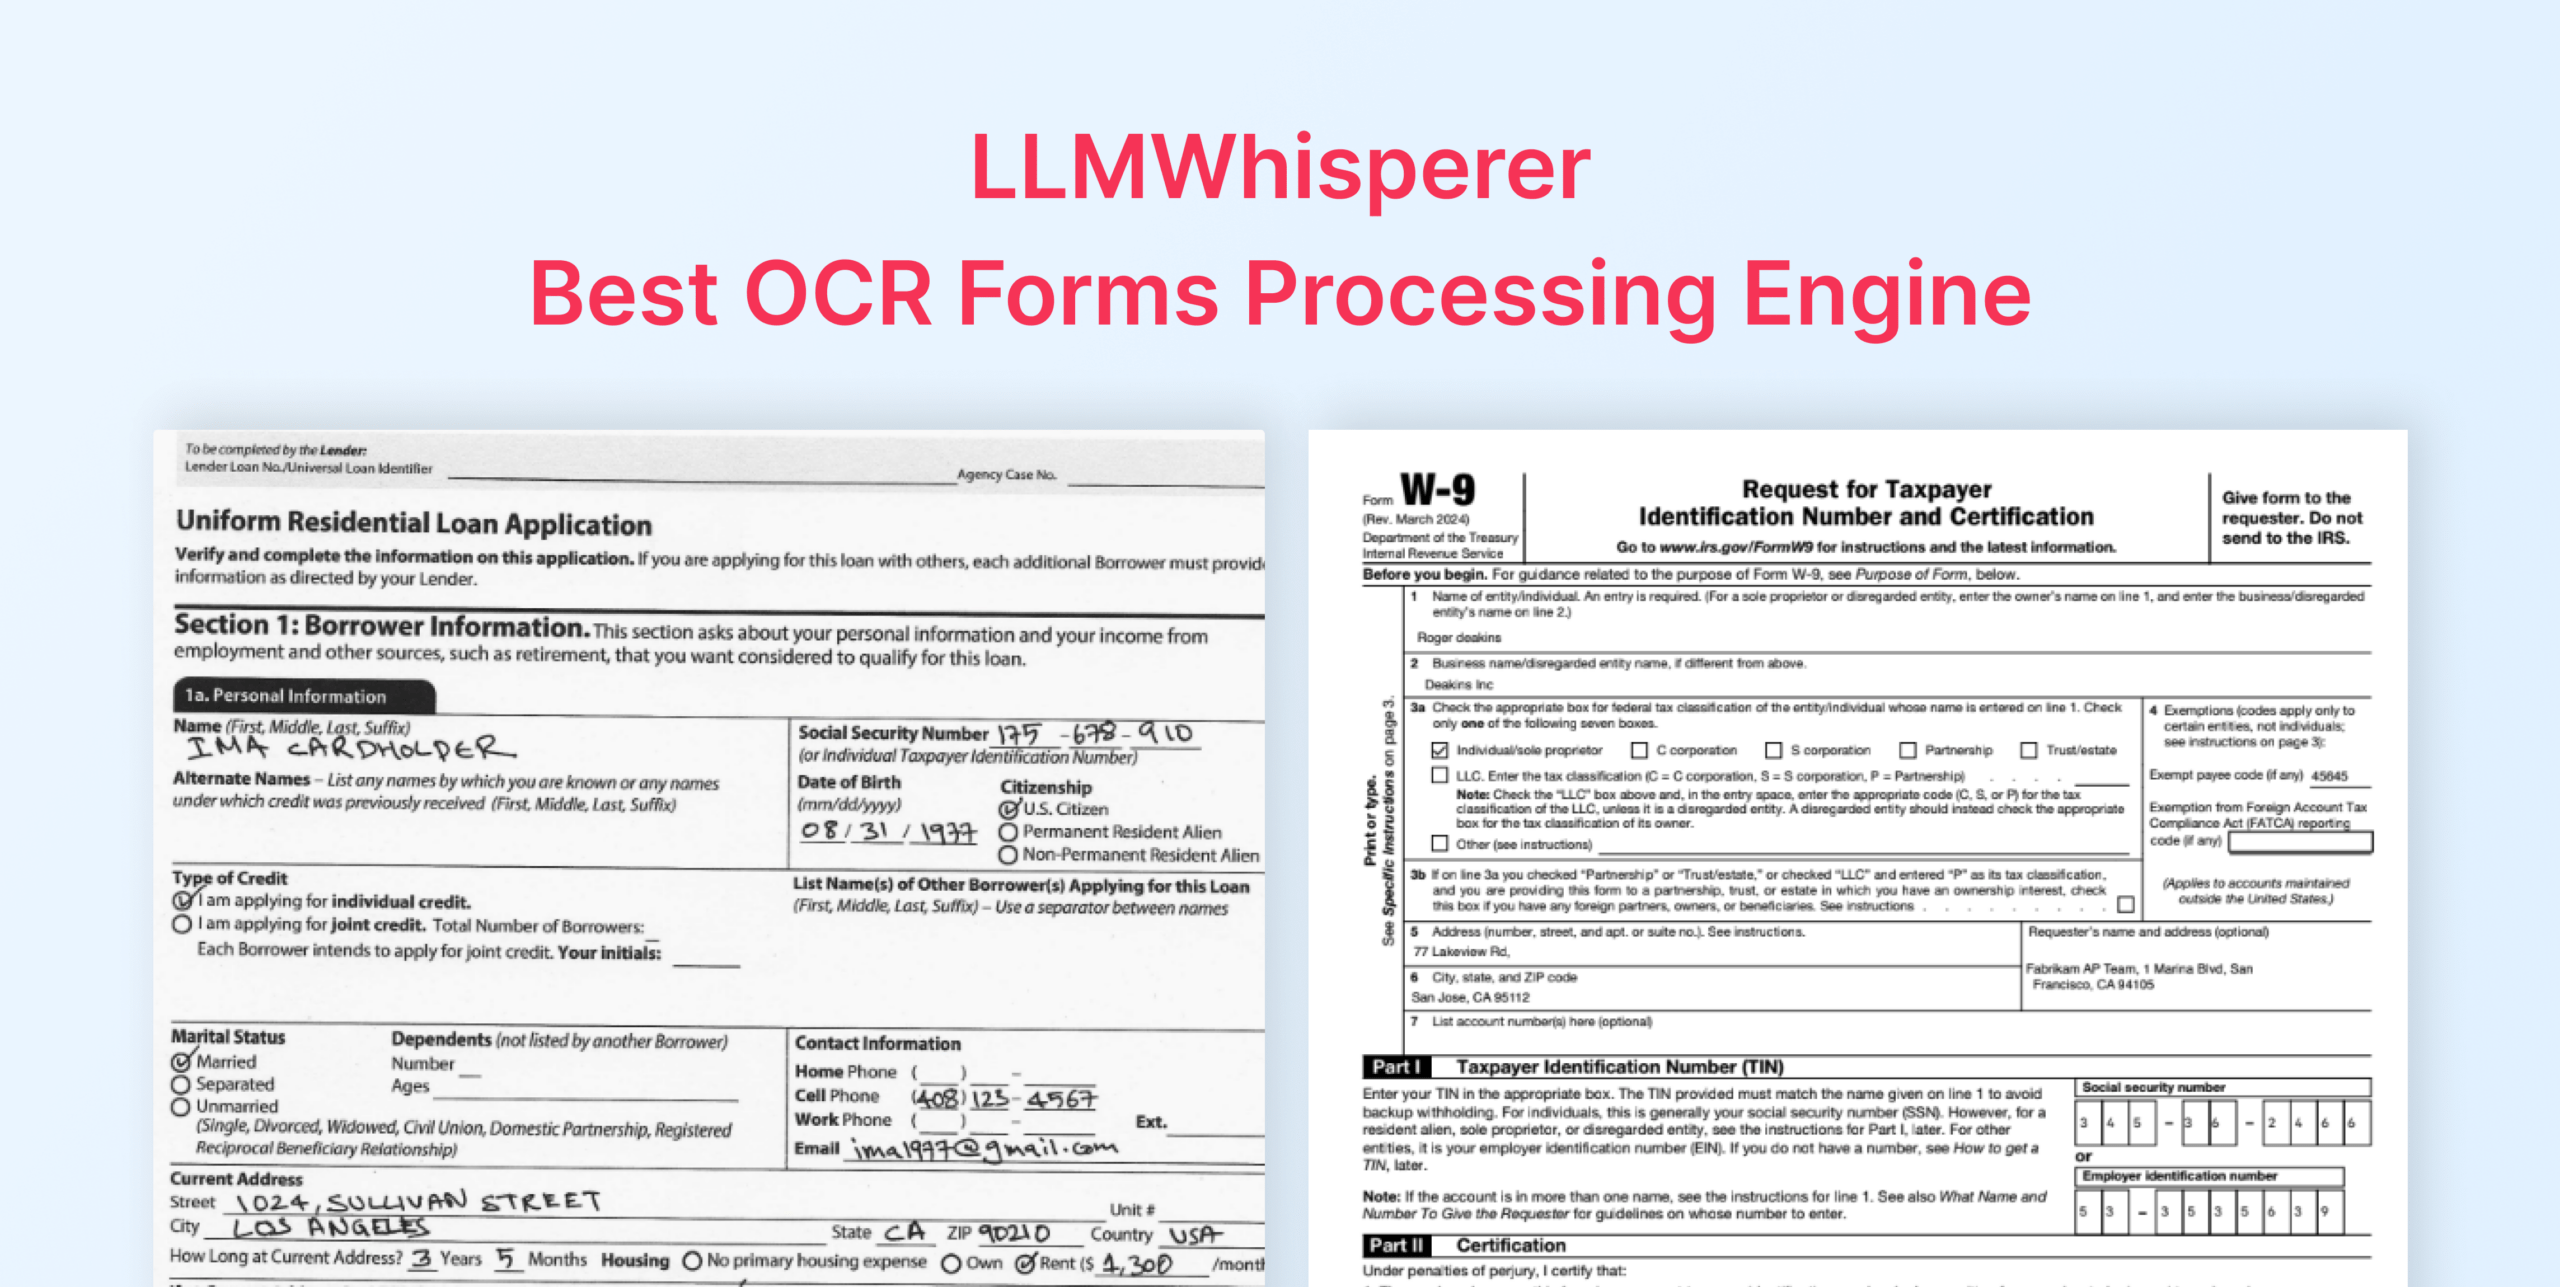
Learn how LLMWhisperer delivers high-accuracy OCR for forms across tax, banking, KYC, insurance, logistics, and government workflows.
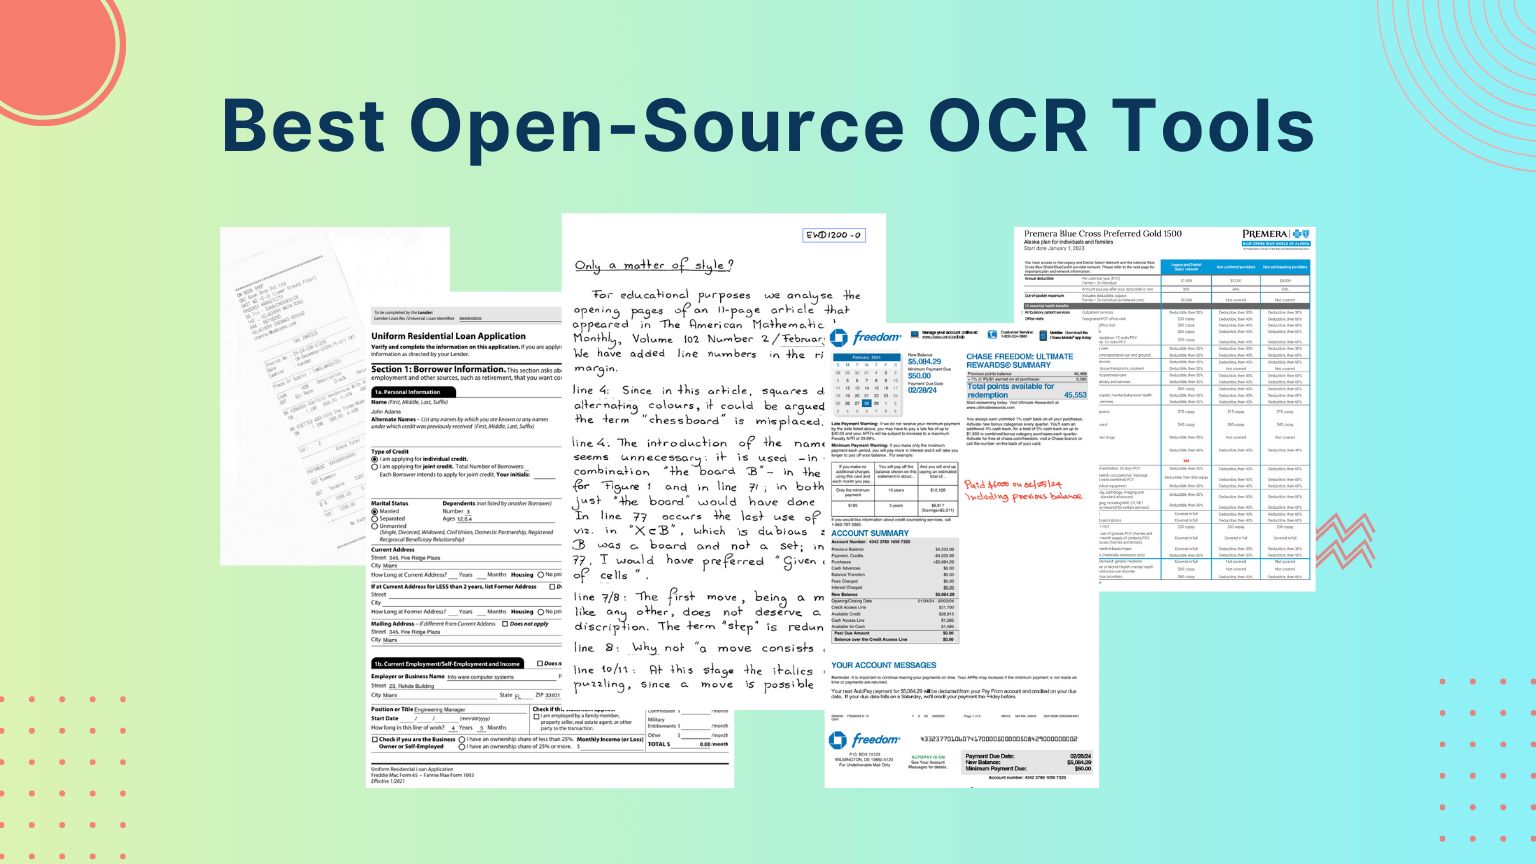
Discover the best opensource OCR tools in this guided listicle—comparing traditional engines and modern LLM-powered approaches, their strengths, limitations, and real-world use cases.
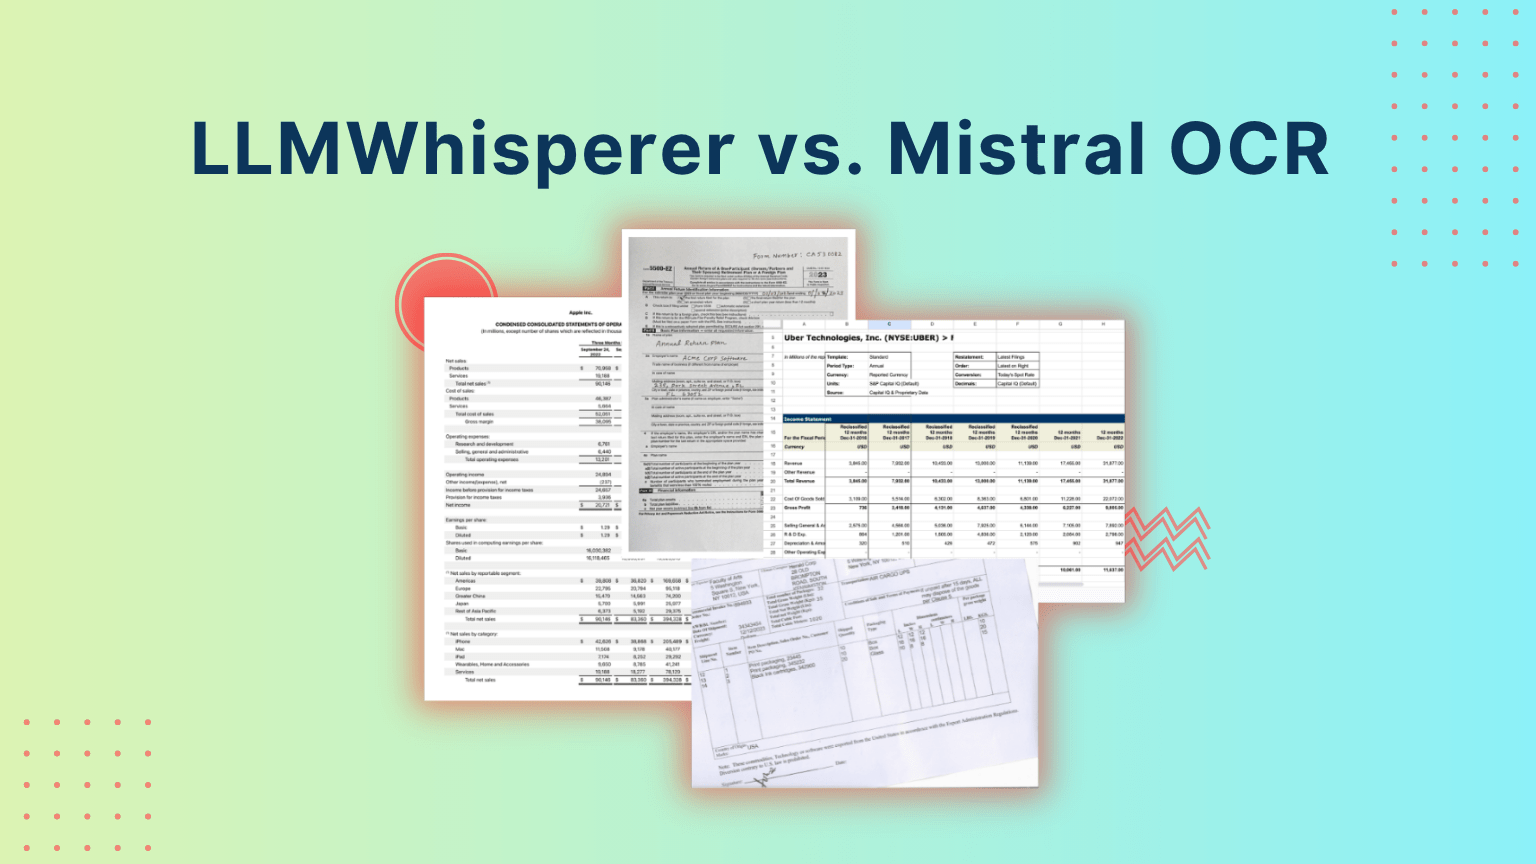
In this article, we put Unstract’s LLMwhisperer and Mistral OCR to the test using a series of challenging sample documents. We’ll explore their outputs and wrap up with practical recommendations for which tool to use and when.
This piece explores the difficulties of processing scanned handwritten PDFs with form fields and showcases how large language models (LLMs) offer innovative approaches to fillable field data extraction.
This piece explores the difficulties of processing scanned PDFs and image scans and showcases how large language models (LLMs) offer innovative approaches to document text extraction.