Product
High Accuracy OCR in 2026: Why LLMWhisperer is the Most Accurate OCR
Why Use LLMWhisperer?
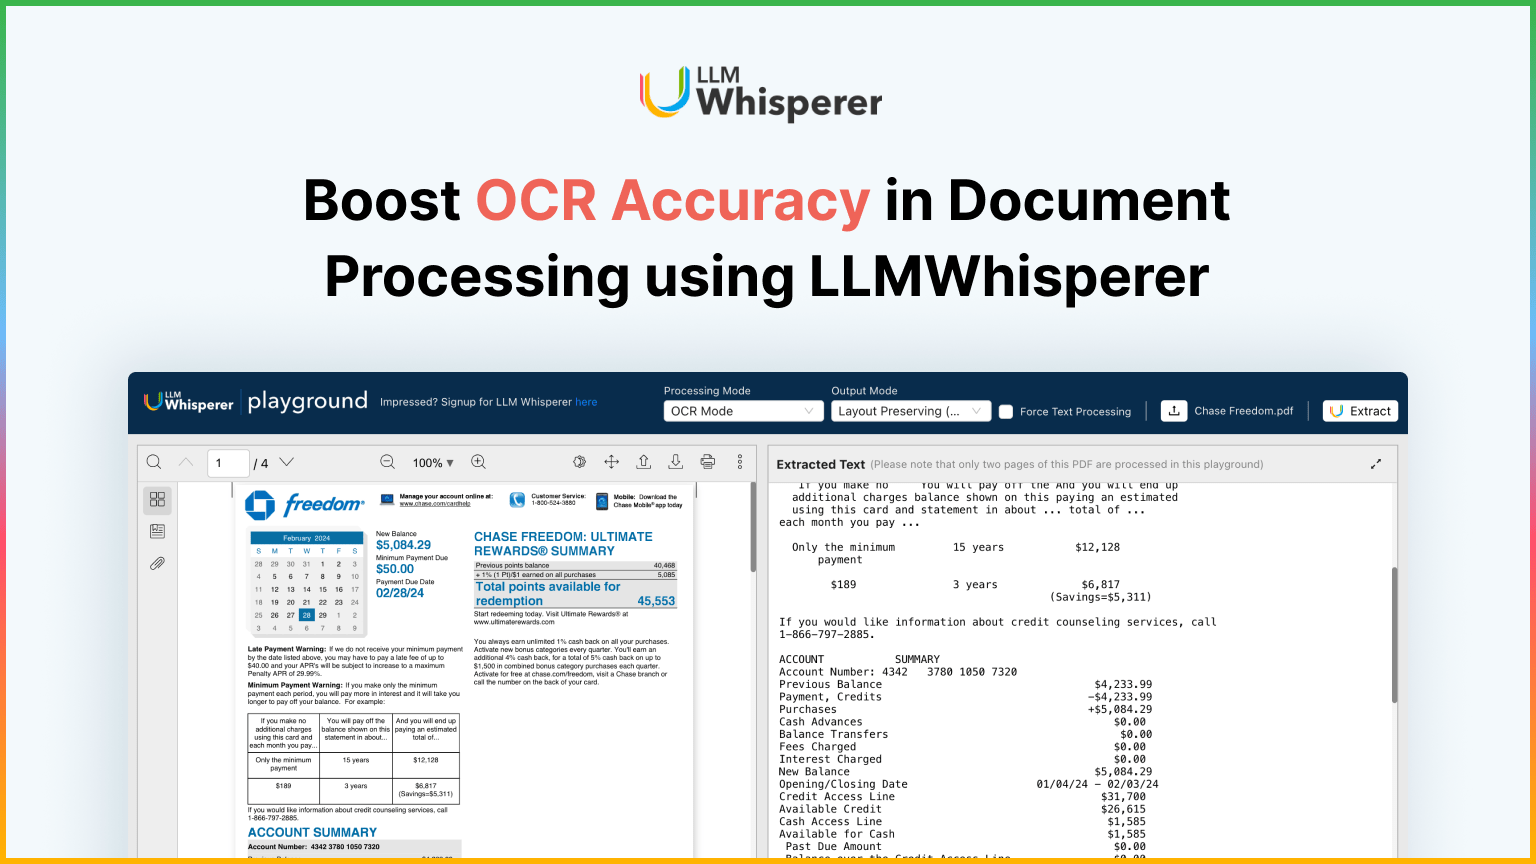
Traditional OCR fails with complex documents. LLMWhisperer delivers high-accuracy OCR for real-world business needs.

Why Use LLMWhisperer?
Traditional OCR fails with complex documents. LLMWhisperer delivers high-accuracy OCR for real-world business needs.
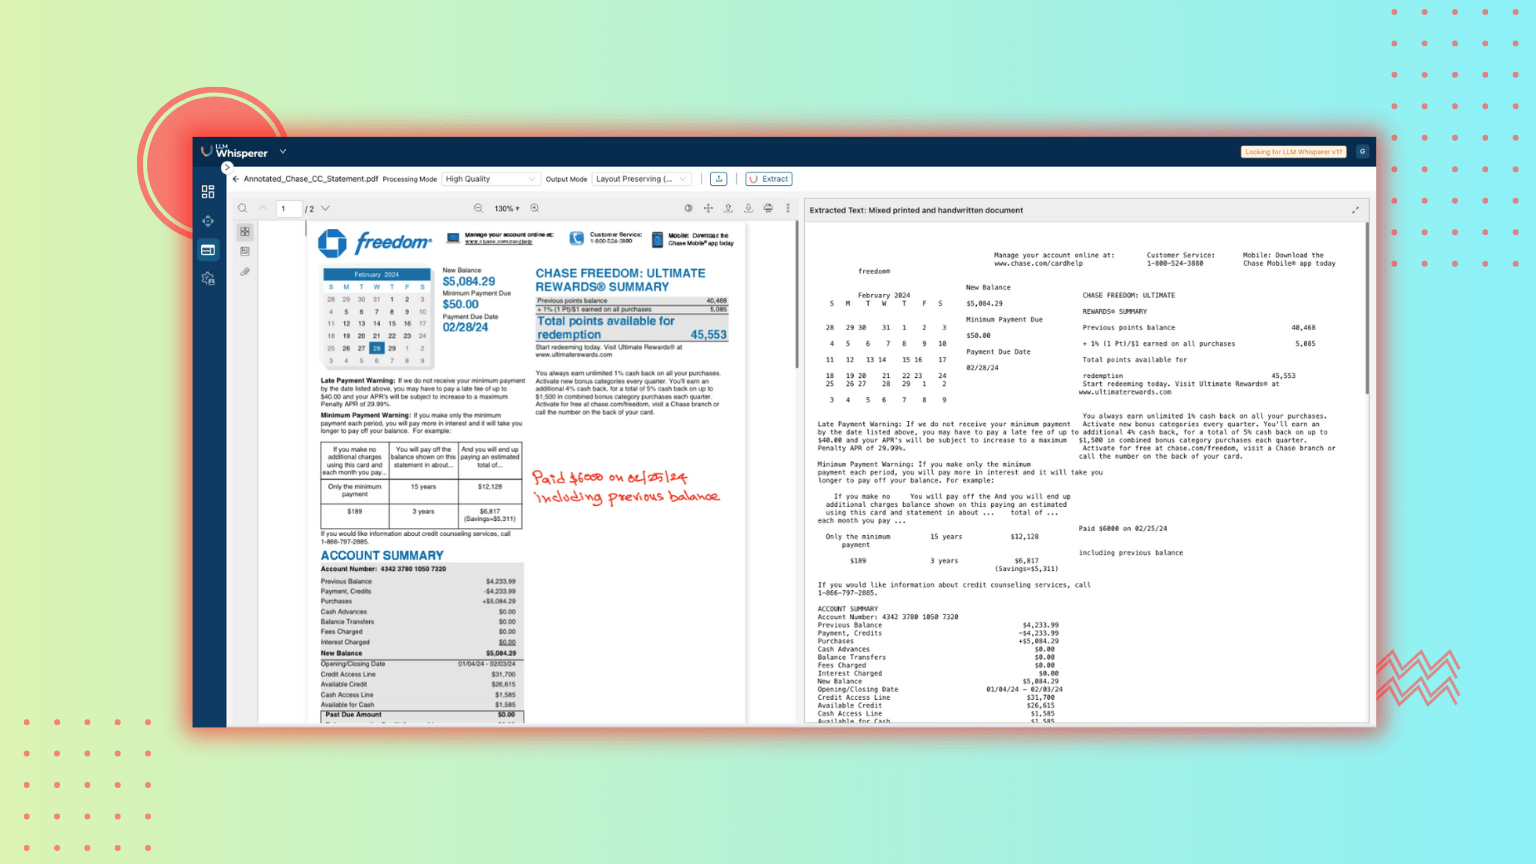
Looking for the best OCR for bookkeeping? LLMWhisperer goes beyond traditional OCR by accurately handling complex financial documents, —delivering clean, structured data ready for downstream use. Learn more.

In this blog, we’ll explore the challenges engineers face when processing purchase orders. We’ll also highlight the purchase order OCR capabilities of LLMWhisperer and demonstrate how Unstract streamlines data extraction from purchase orders.

What is contract data extraction? Contract processing refers to the systematic management of contracts throughout their lifecycle, from creation and
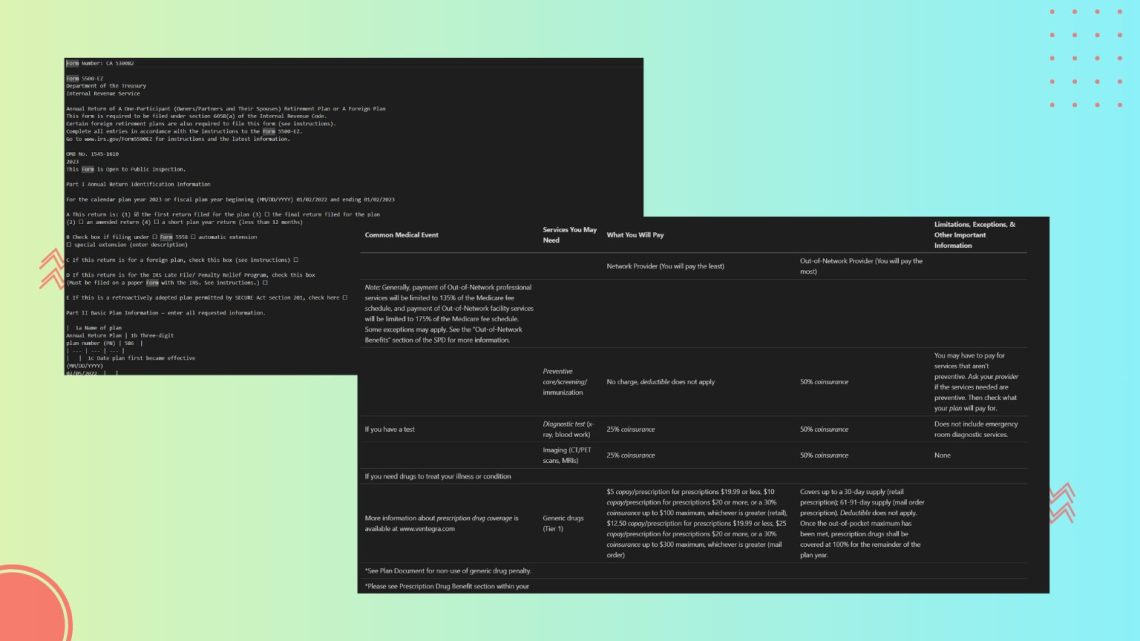
Markdown-based OCR falls short for LLM-driven structured data extraction. This article compares it with LLMWhisperer, a layout-preserving OCR built for LLM pre-processing, highlighting how retaining spatial structure and confidence scores enables more accurate downstream extraction.
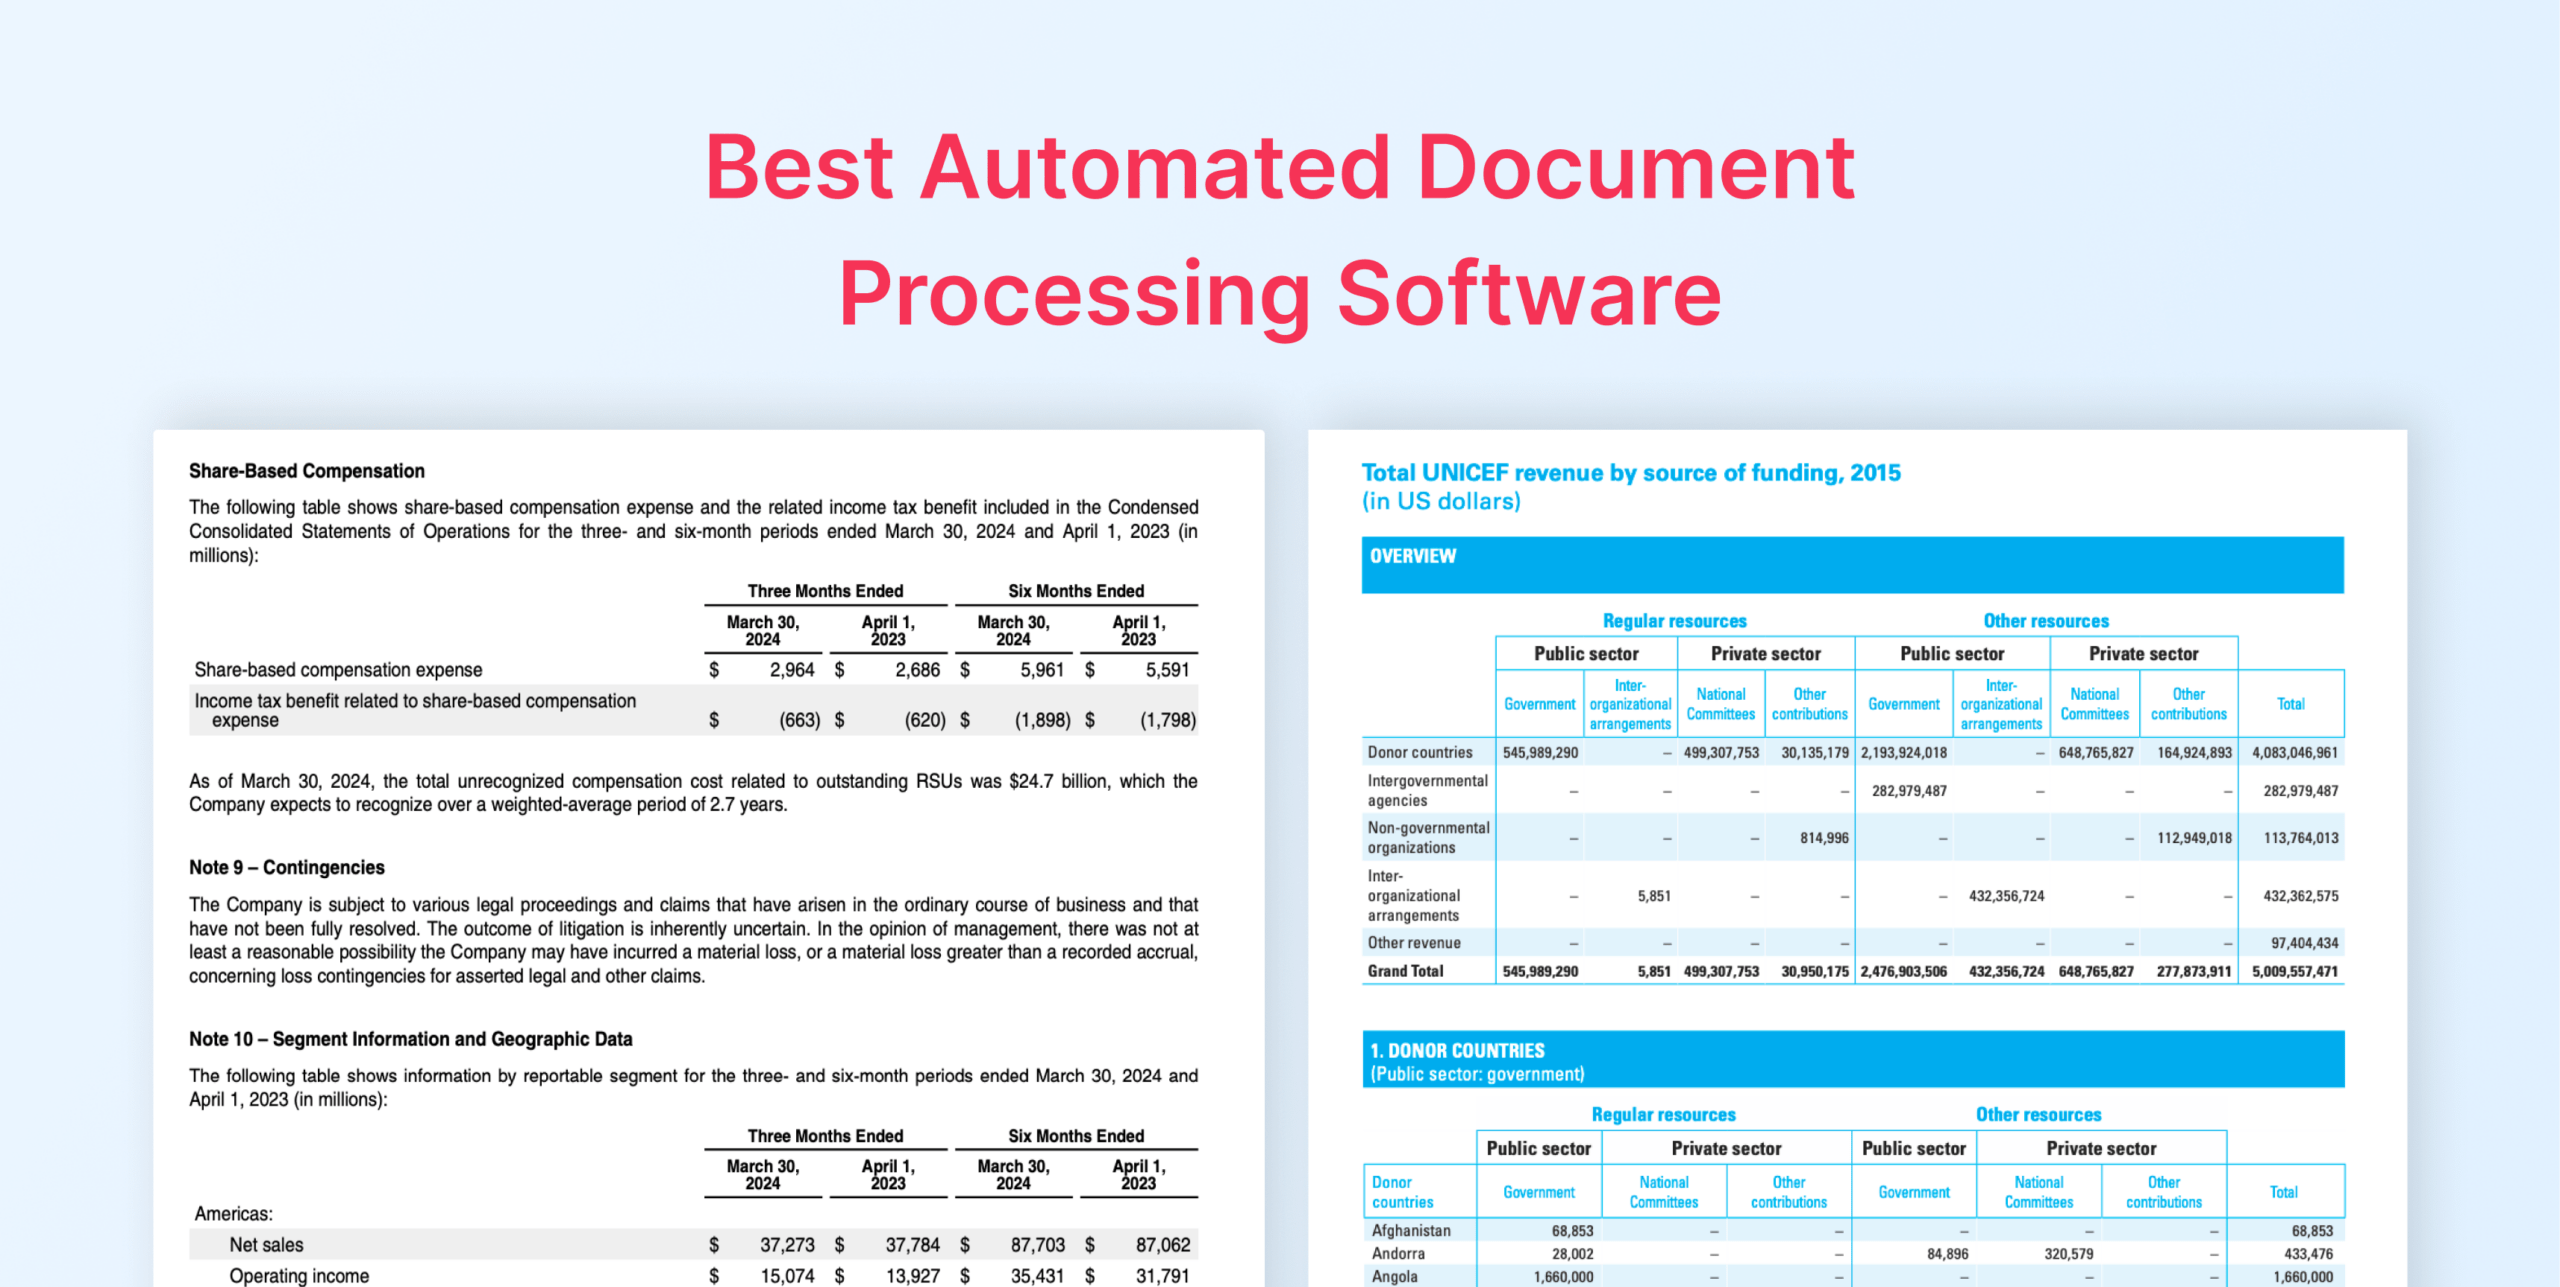
Explore automated document processing software built for variability. Handle scanned PDFs, handwritten forms, and complex layouts with built-in accuracy scoring and API-first deployment.