LLMWhisperer is a document OCR engine purpose-built for LLM pipelines. Get clean, layout-preserved text from PDFs, images, scans, handwriting and more.
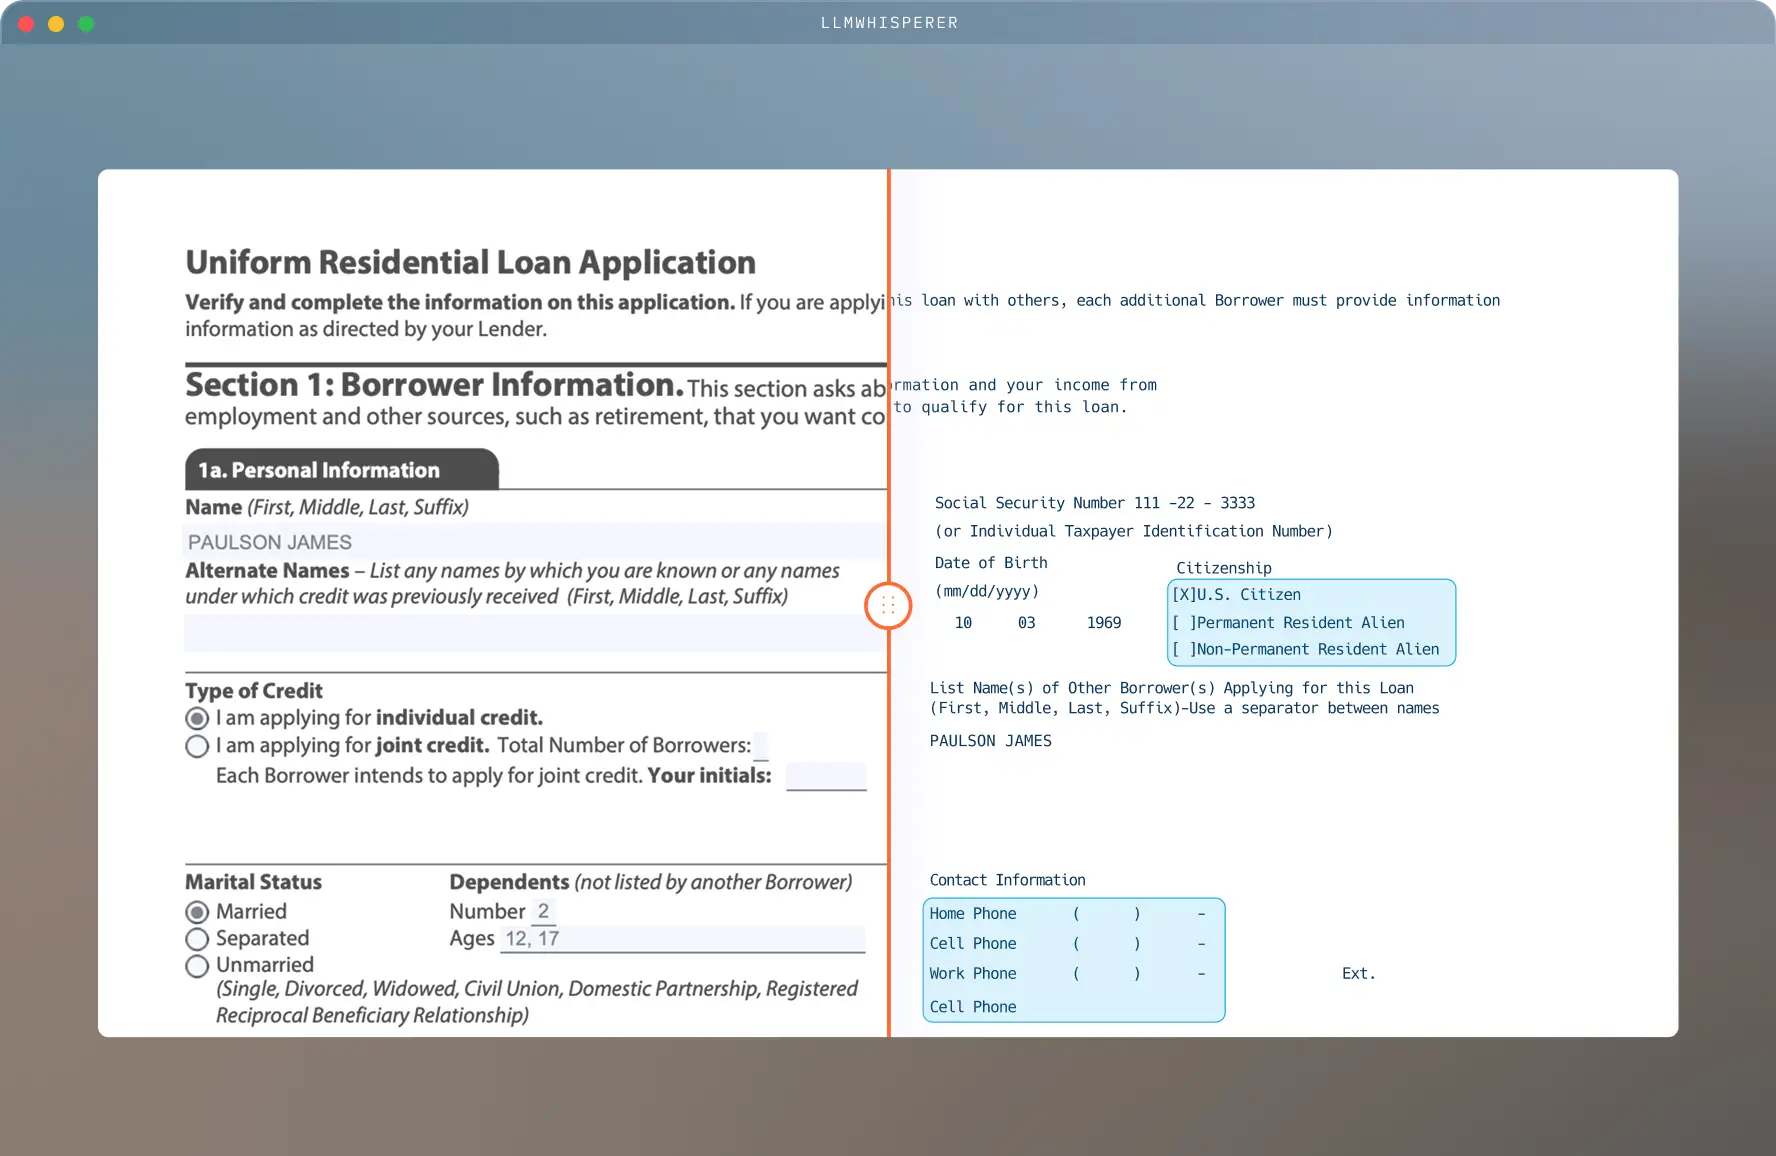
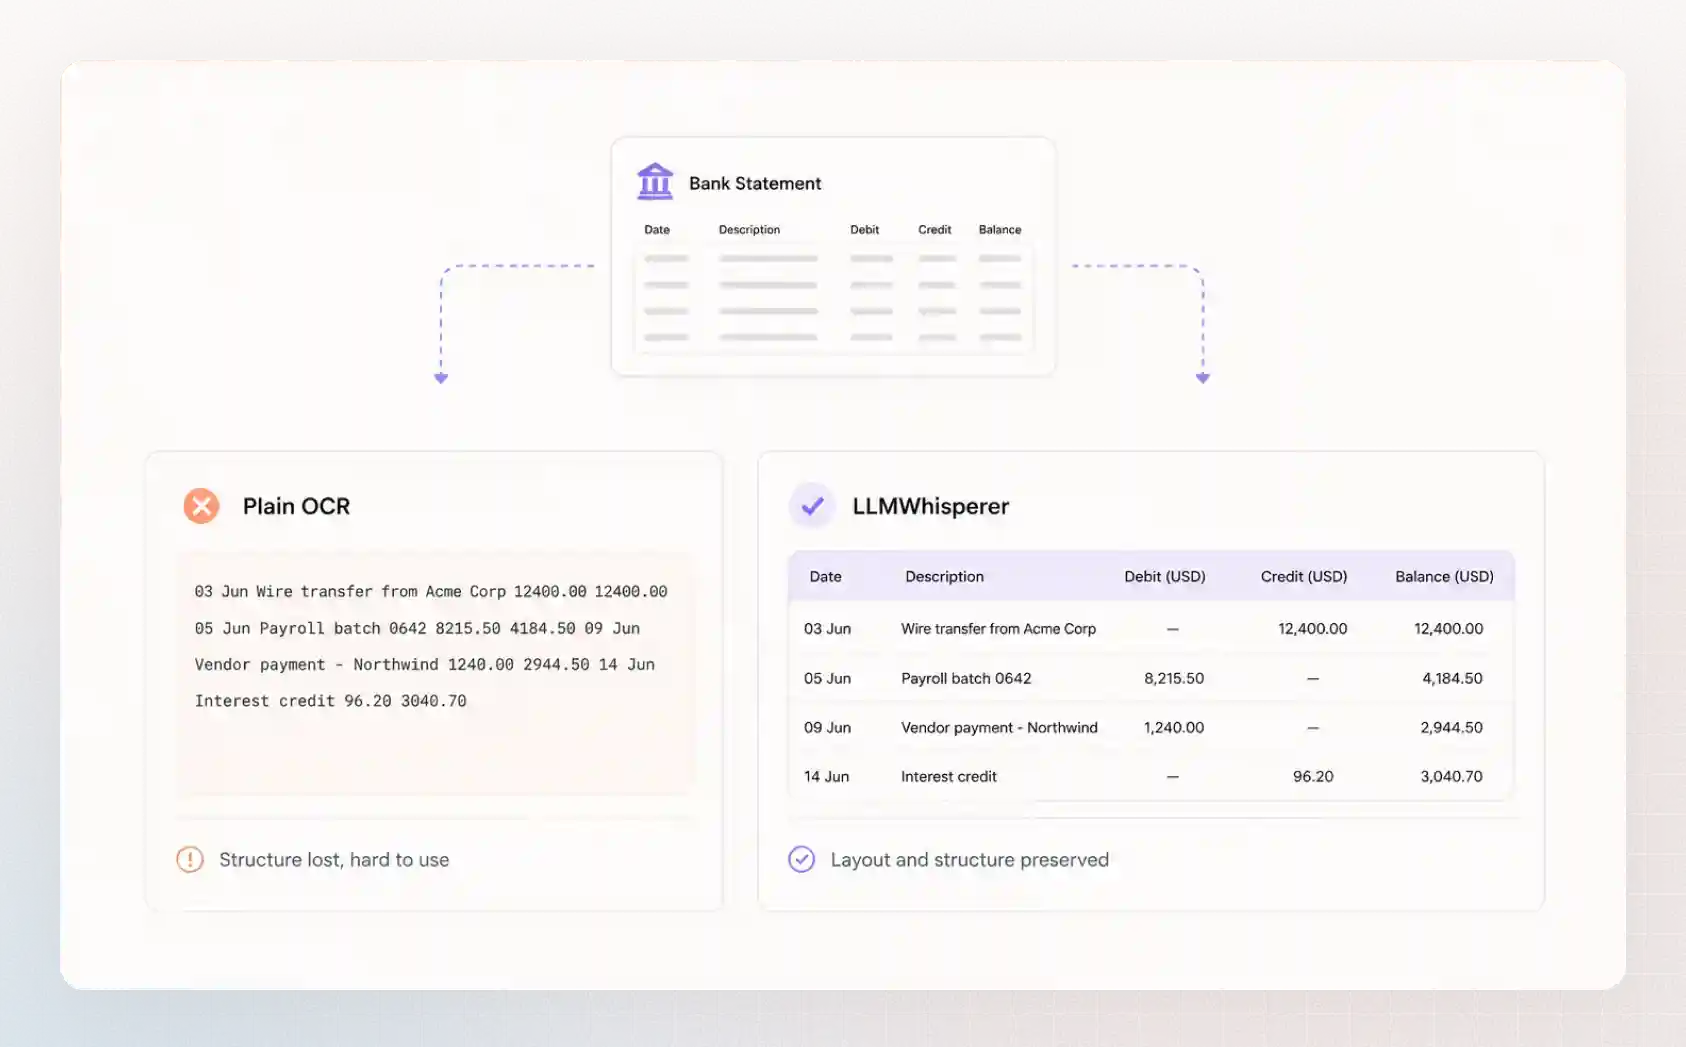
LLMWhisperer parses documents into text LLMs can read. Headers in place. Tables that look like tables. Checkboxes marked. Columns in the right order.
Layout-preserved text, every time
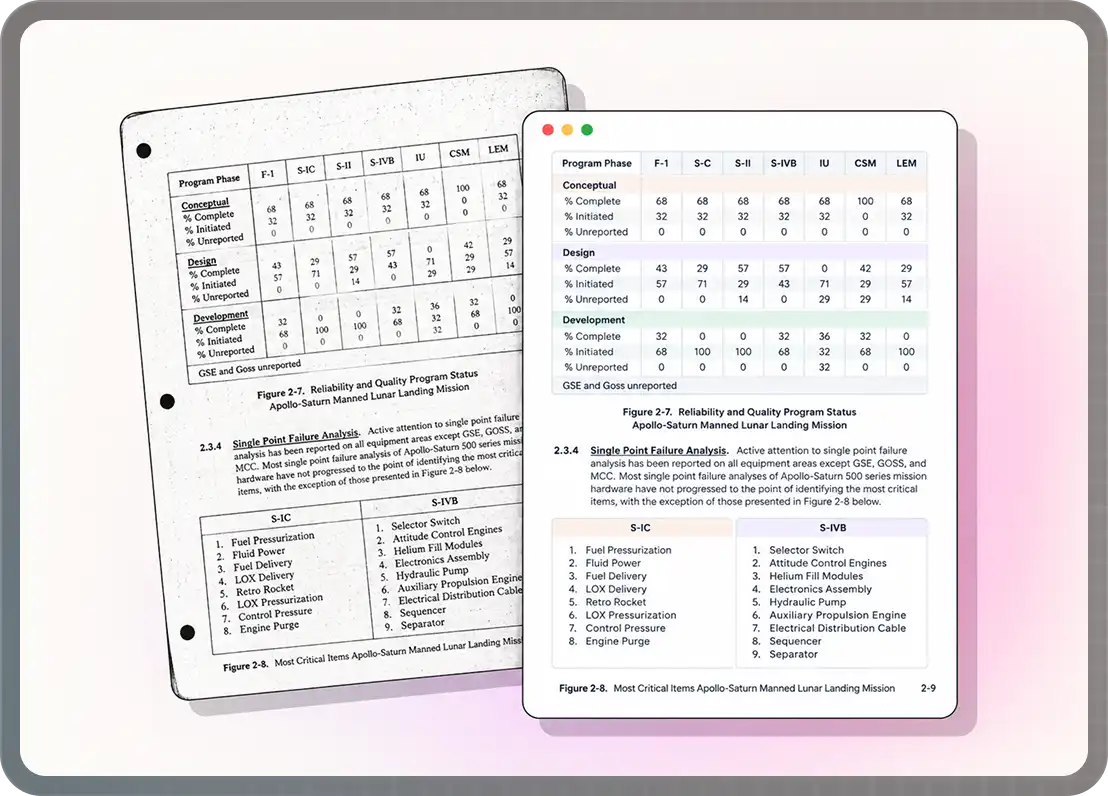
Complex documents carry meaning in their structure, not just their words: tables, checkboxes, multi-column layouts. LLMWhisperer preserves that structure exactly as designed, so nothing gets lost in translation. You get accurate extraction from even the messiest real-world documents, without manual cleanup.
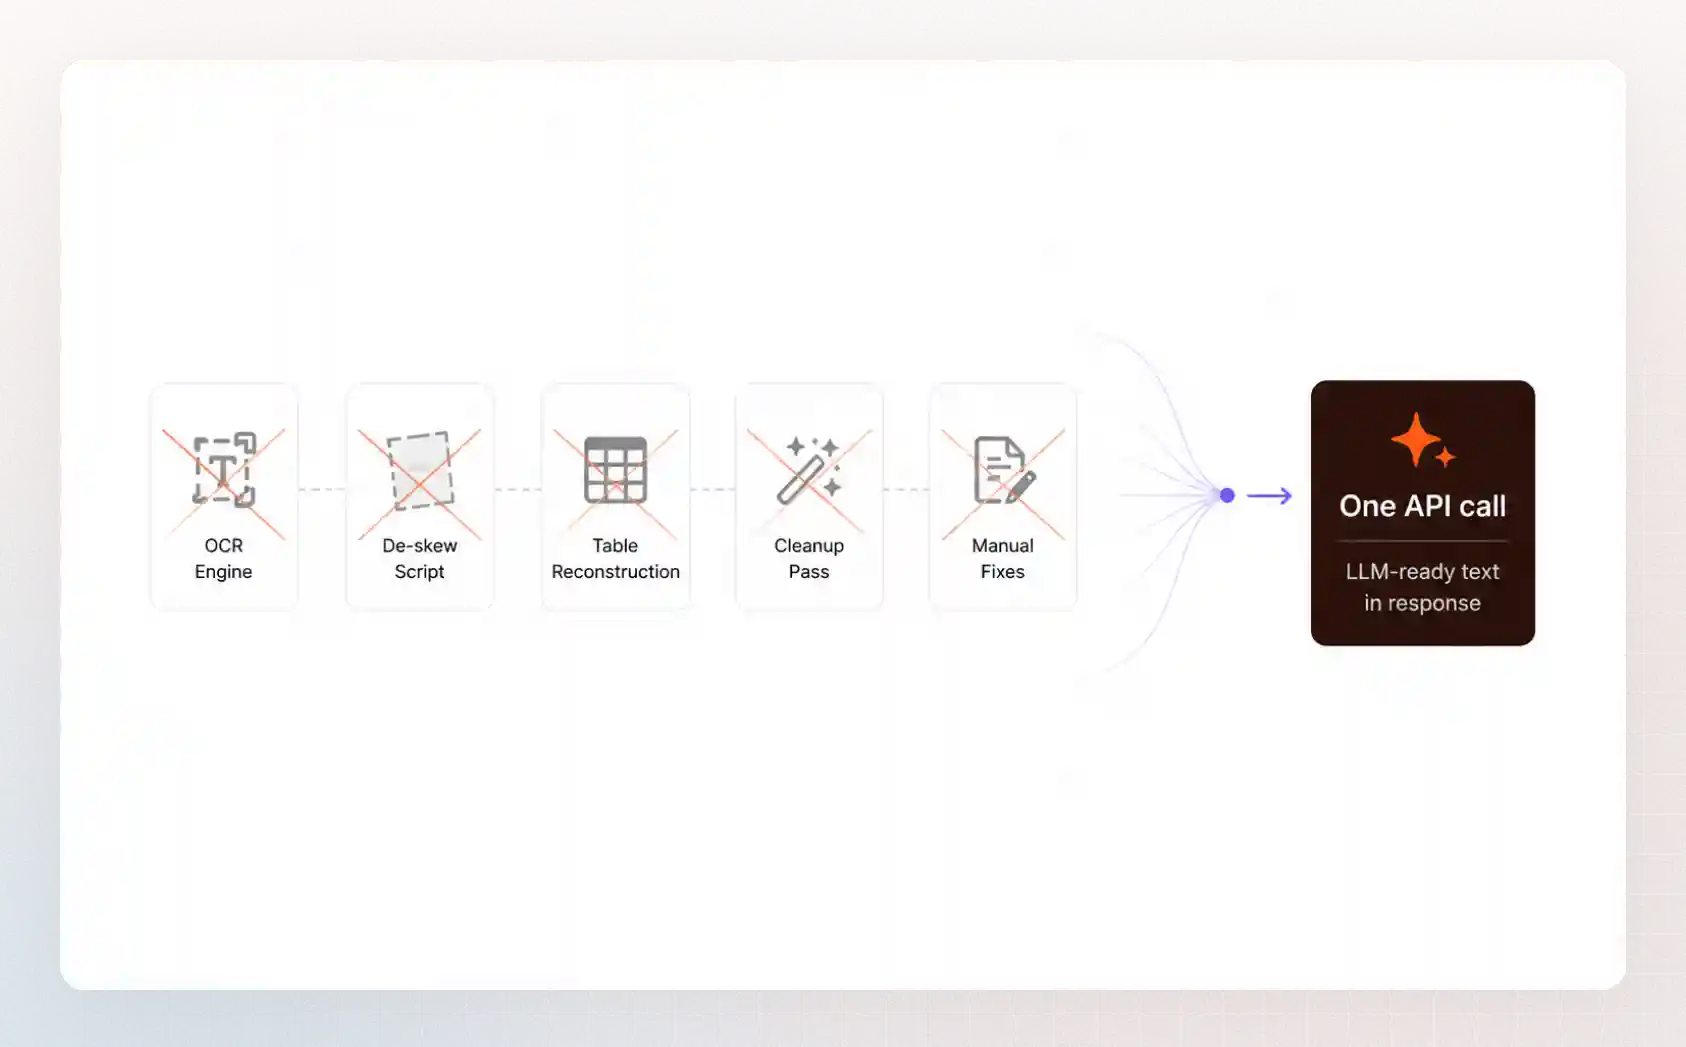
Document parsing usually means stitching together an OCR engine, de-skew scripts, table reconstruction, and a cleanup pass. LLMWhisperer replaces that pile with one API call that returns LLM-ready text.
Every document gets the processing it needs, nothing more. Run clean PDFs through the default mode and save the heavy-duty for the hard ones with instant mode-switching. No commitment for your whole workload.
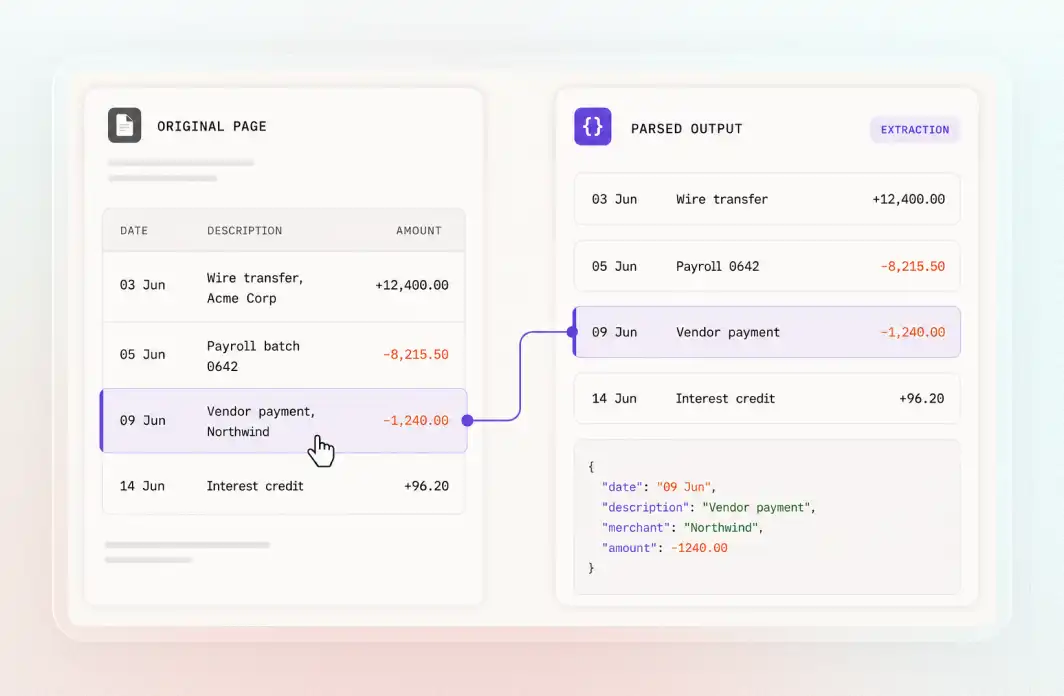
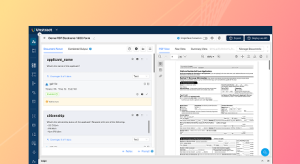
Stop taking extractions on faith. The Highlight API shows exactly where on the original page each answer came from. Human review, audits, and compliance become second nature instead of a chore.
Stop taking extractions on faith. The Highlight API shows exactly where on the original page each answer came from. Human review, audits, and compliance become second nature instead of a chore.
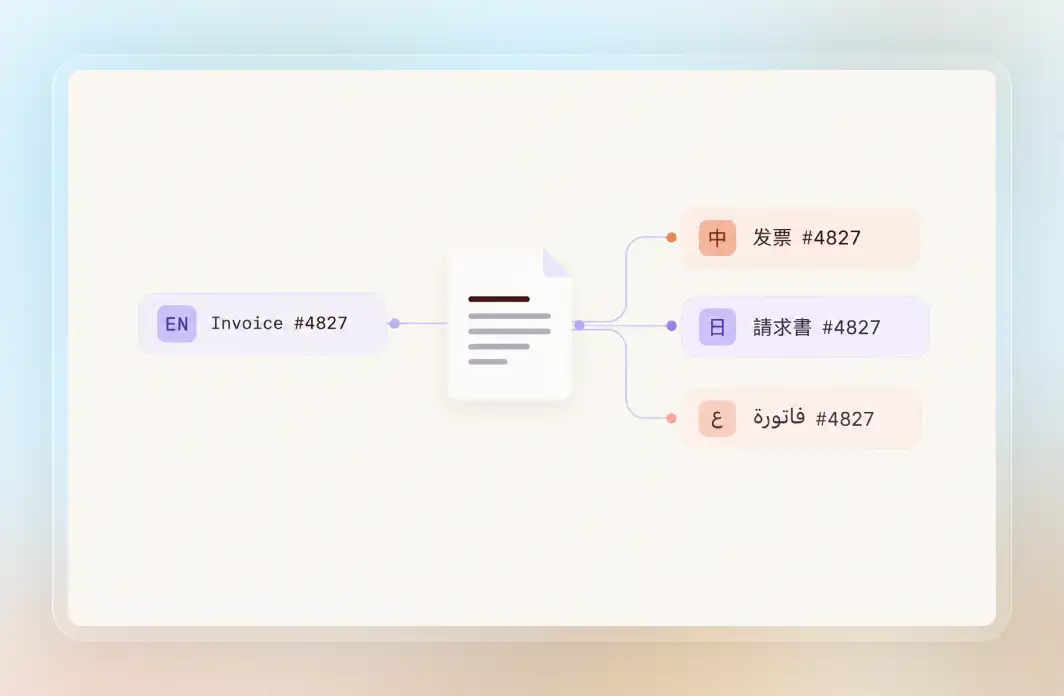
LLMWhisperer reads 300+ printed languages and handwriting in 12, including English, Chinese, Japanese, and Arabic. Nothing additional to install, nothing to configure, no additional charge.
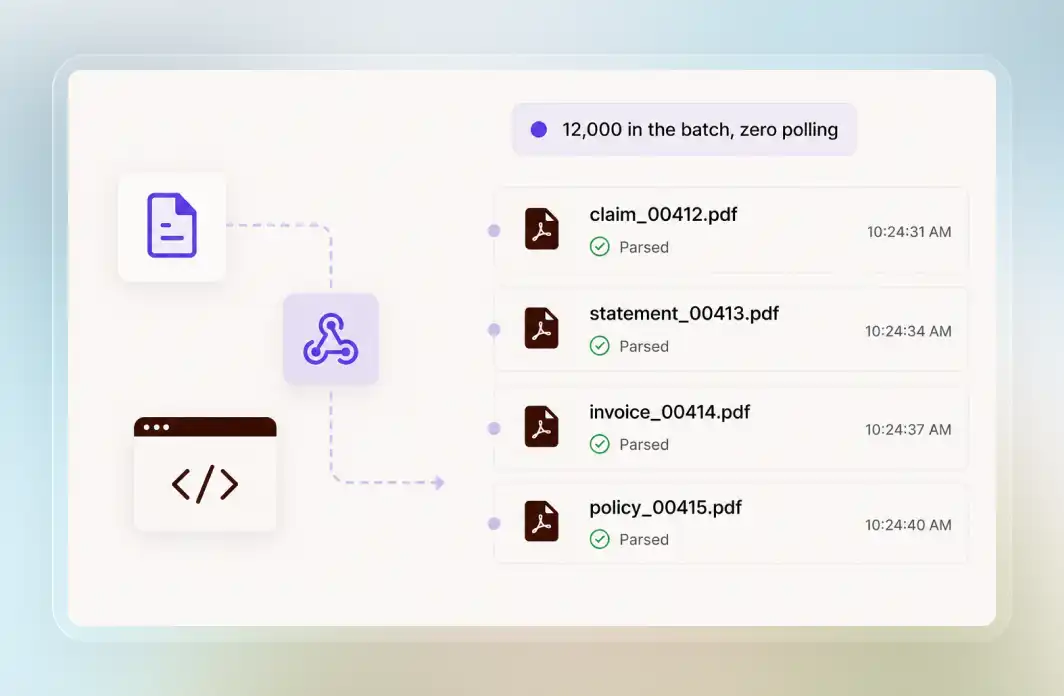
The simple path is the default: send a document, get clean text. When the batch gets big, Webhooks stream to your endpoint as soon as parsing is done. No polling, no babysitting.
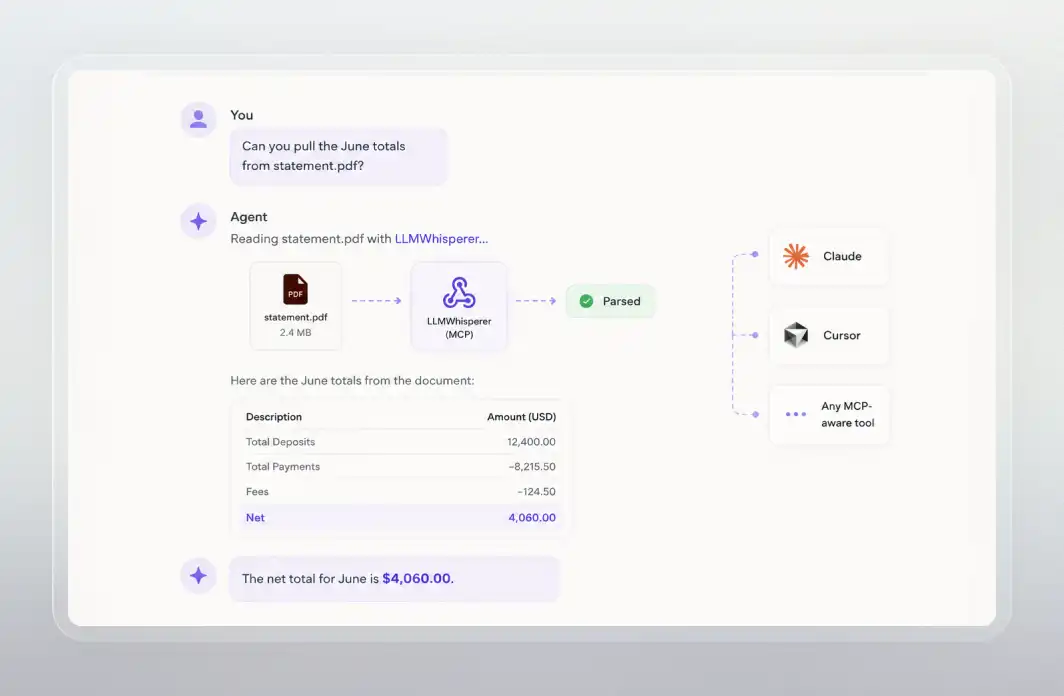
LLMWhisperer is the parsing engine behind Unstract, the agentic document extraction platform. Unstract lets you define the fields you want to extract and deploy the result as an API, or run ETL pipelines right to production.
Fully managed. Sign up, get an API key, start parsing in under a minute. 100 pages a day free, forever.
On-Premise
Runs inside your AWS, Azure, or GCP VPC. Documents never leave your network. Same API, same modes, same output.
Integrations
Python and JavaScript clients drop into your codebase. An n8n custom node brings parsing to no-code automations. A Postman collection lets you try every call before you write one.
What customers say
BEATS OCR ENGINES & PARSERS
It outperformed every other tool I tested.
I value how accurately it converts complex PDFs into clean text, even when the tables have unusual or inconsistent structures. It beat every OCR engine and PDF parser I tried. That reliability makes it easy to embed in a fully automated monitoring and prospecting pipeline, from PDF conversion through to field extraction with another LLM. The result is a faster, more scalable workflow with no manual effort.
Marie-Ange Rasendra
Heva Data
CHECKBOXES / HEALTHCARE DOCUMENTS
Checkboxes matter to us, and it nails them every time.
LLMWhisperer extracts data from our PDF documents quickly and accurately. Proper handling of checkboxes is of utmost importance to us, and it gets them right every time. We use it daily in our healthcare business to process unstructured clinical data that only comes in PDF form, then feed the clean output into an LLM for further processing.
Ray Laurinavicius
Datajo
PRODUCTION AT SCALE
Finally, a document extractor that's almost 100%.
I used the API to process over 10,000 individual PDFs. Built-in options like switching the quality mode and bounding tables were super helpful. Extraction speed and accuracy were core to the product we were launching, and when you compare the accuracy and organisation of LLMWhisperer’s output against tools like PDF.co, it was night and day.
Greg Crisci
Advisor
DEVELOPER EXPERIENCE
Unbeatable speed and quality, easily integrable.
Easy integration into my existing systems was the most important point for me, and it’s very developer-friendly. Processing speed is unbeatable while maintaining unbeatable quality. I control in the request which information I want back and in what format. Table recognition for line items on invoices and delivery notes is unbeatable, and so is the cost in this segment.
Unstract adheres to the strict rules and regulations of various compliance authorities. Rest assured, we have policies, systems, and processes to ensure that your data is always safe, secure, and private.